Muhammad Naufil

AI Engineer  Β·  MS CS @ Saarland University

I build AI systems at the intersection of computer vision, LLMs, and agentic workflows. Currently a Werkstudent at Mercedes-Benz, turning camera and LiDAR recordings into ML-ready datasets for autonomous driving, and a Research Assistant at Saarland University, where I'm pursuing an MS in Computer Science. My Master thesis at MPI Informatics is on group co-speech gesture synthesis with latent diffusion.

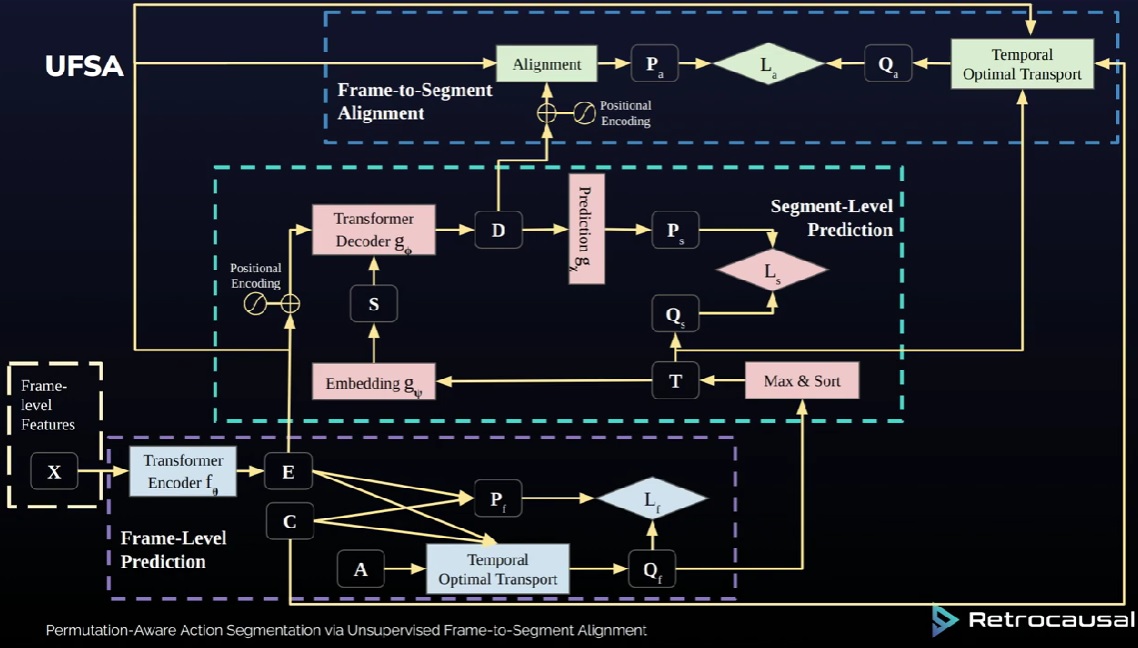
Previously a Computer Vision Working Student at CISPA startup Detesia on deepfake detection, finetuning vision foundation models on clusters of 8Γ—A100 GPUs. I was also founding engineer at Gordian Robotics working on retail shelf monitoring, a HiWi at MPI Informatics working with diffusion models for gesture generation, and a Research Assistant at Zema exploring RAG and AI agents. Before my Master's I spent 3+ years as a Computer Vision Engineer at Retrocausal (Redmond, WA), where I built markerless MoCap that won a $150K/yr contract with Siemens, and action segmentation we piloted with Honda, Suzuki, and Nissan.

On the side I ship my own products: 10 Sentences, a German learning platform with 100+ users; Batcheet, a 30K+ node trust graph for referral hiring; LinkInsertion.ai, an agentic outreach tool with paying customers; and SyncMyTime, a time and weather database for remote teams.
Work Experience

Mercedes-Benz
Werkstudent β€” Autonomous Driving Data
Mercedes-Benz  |  Stuttgart  Β·  Aug 2026 – Present

Developing data processing pipelines that transform raw camera and LiDAR ROS bag recordings into structured, ML-ready datasets for training autonomous driving models.

Saarland University
Research Assistant β€” Sign Language & Co-Speech Gestures
Saarland University  |  SaarbrΓΌcken  Β·  Jul 2026 – Present

Working on understanding sign language and co-speech gestures through phonemes.

MPI Informatics
MPI Informatics  |  SaarbrΓΌcken  Β·  MS Computer Science, Saarland University
  • Built a speech- and text-conditioned 3D gesture generation model with latent diffusion: a Transformer (DiT) denoises in latent space, conditioned on T5 text and mel-spectrogram audio features via cross-attention.
  • Generates full-body SMPL-X motion (body, fingers, locomotion) at scale on the BEAT2, Embody3D and DnD datasets.
  • Research questions: making characters spatially and socially aware, preventing collisions while keeping positions and orientations right for mutual gaze, encoding multi-participant speech cheaply, and scaling to any number of participants.
CISPA
Computer Vision Working Student β€” Deepfake Detection
Detesia  |  CISPA Startup  Β·  Oct 2024 – Dec 2025
  • Finetuned vision foundation models on a large-scale collection of deepfakes using clusters of 8Γ—A100 GPUs.
  • Generated deepfakes at scale with state-of-the-art open- and closed-source generative models to expand training coverage.
  • Found that every generative model leaves a very different feature distribution, so the detector has to be finetuned on every new generator that comes out.
Zema
Research Assistant β€” LLMs & AI Agents
Zema  |  SaarbrΓΌcken  Β·  Aug 2024 – Jun 2025

Evaluated instruction-following and few-shot learning of the latest open- and closed-source LLMs. Built a personal AI companion using GPT-4o with function calling and RAG retrieval (Pinecone). Explored agentic frameworks including n8n and crewAI to build AI workflows and automation pipelines.

MPI Informatics
MPI Informatics  |  SaarbrΓΌcken  Β·  Jun – Sep 2024

Built up expertise in diffusion models progressively: started with unconditional image generation, then conditioned models on class labels to understand classifier-free guidance. Then moved to latent diffusion models for monadic co-speech gesture synthesis, first unconditional and then conditioned on speech transcription to generate gestures that naturally accompany spoken language.

πŸ›’
Founding Engineer β€” Retail AI
Gordian Robotics  |  Remote  Β·  Apr – Jun 2024

Developed a one-shot computer vision system for retail shelf monitoring. Evaluated SuperGlue and LightGlue to recognize products from a single reference image and detect out-of-stock items, so the model doesn't need retraining every time packaging changes.

Monocular Camera MoCap System
Retrocausal, Inc.  |  Redmond, WA  Β·  Nov 2020 – Mar 2024

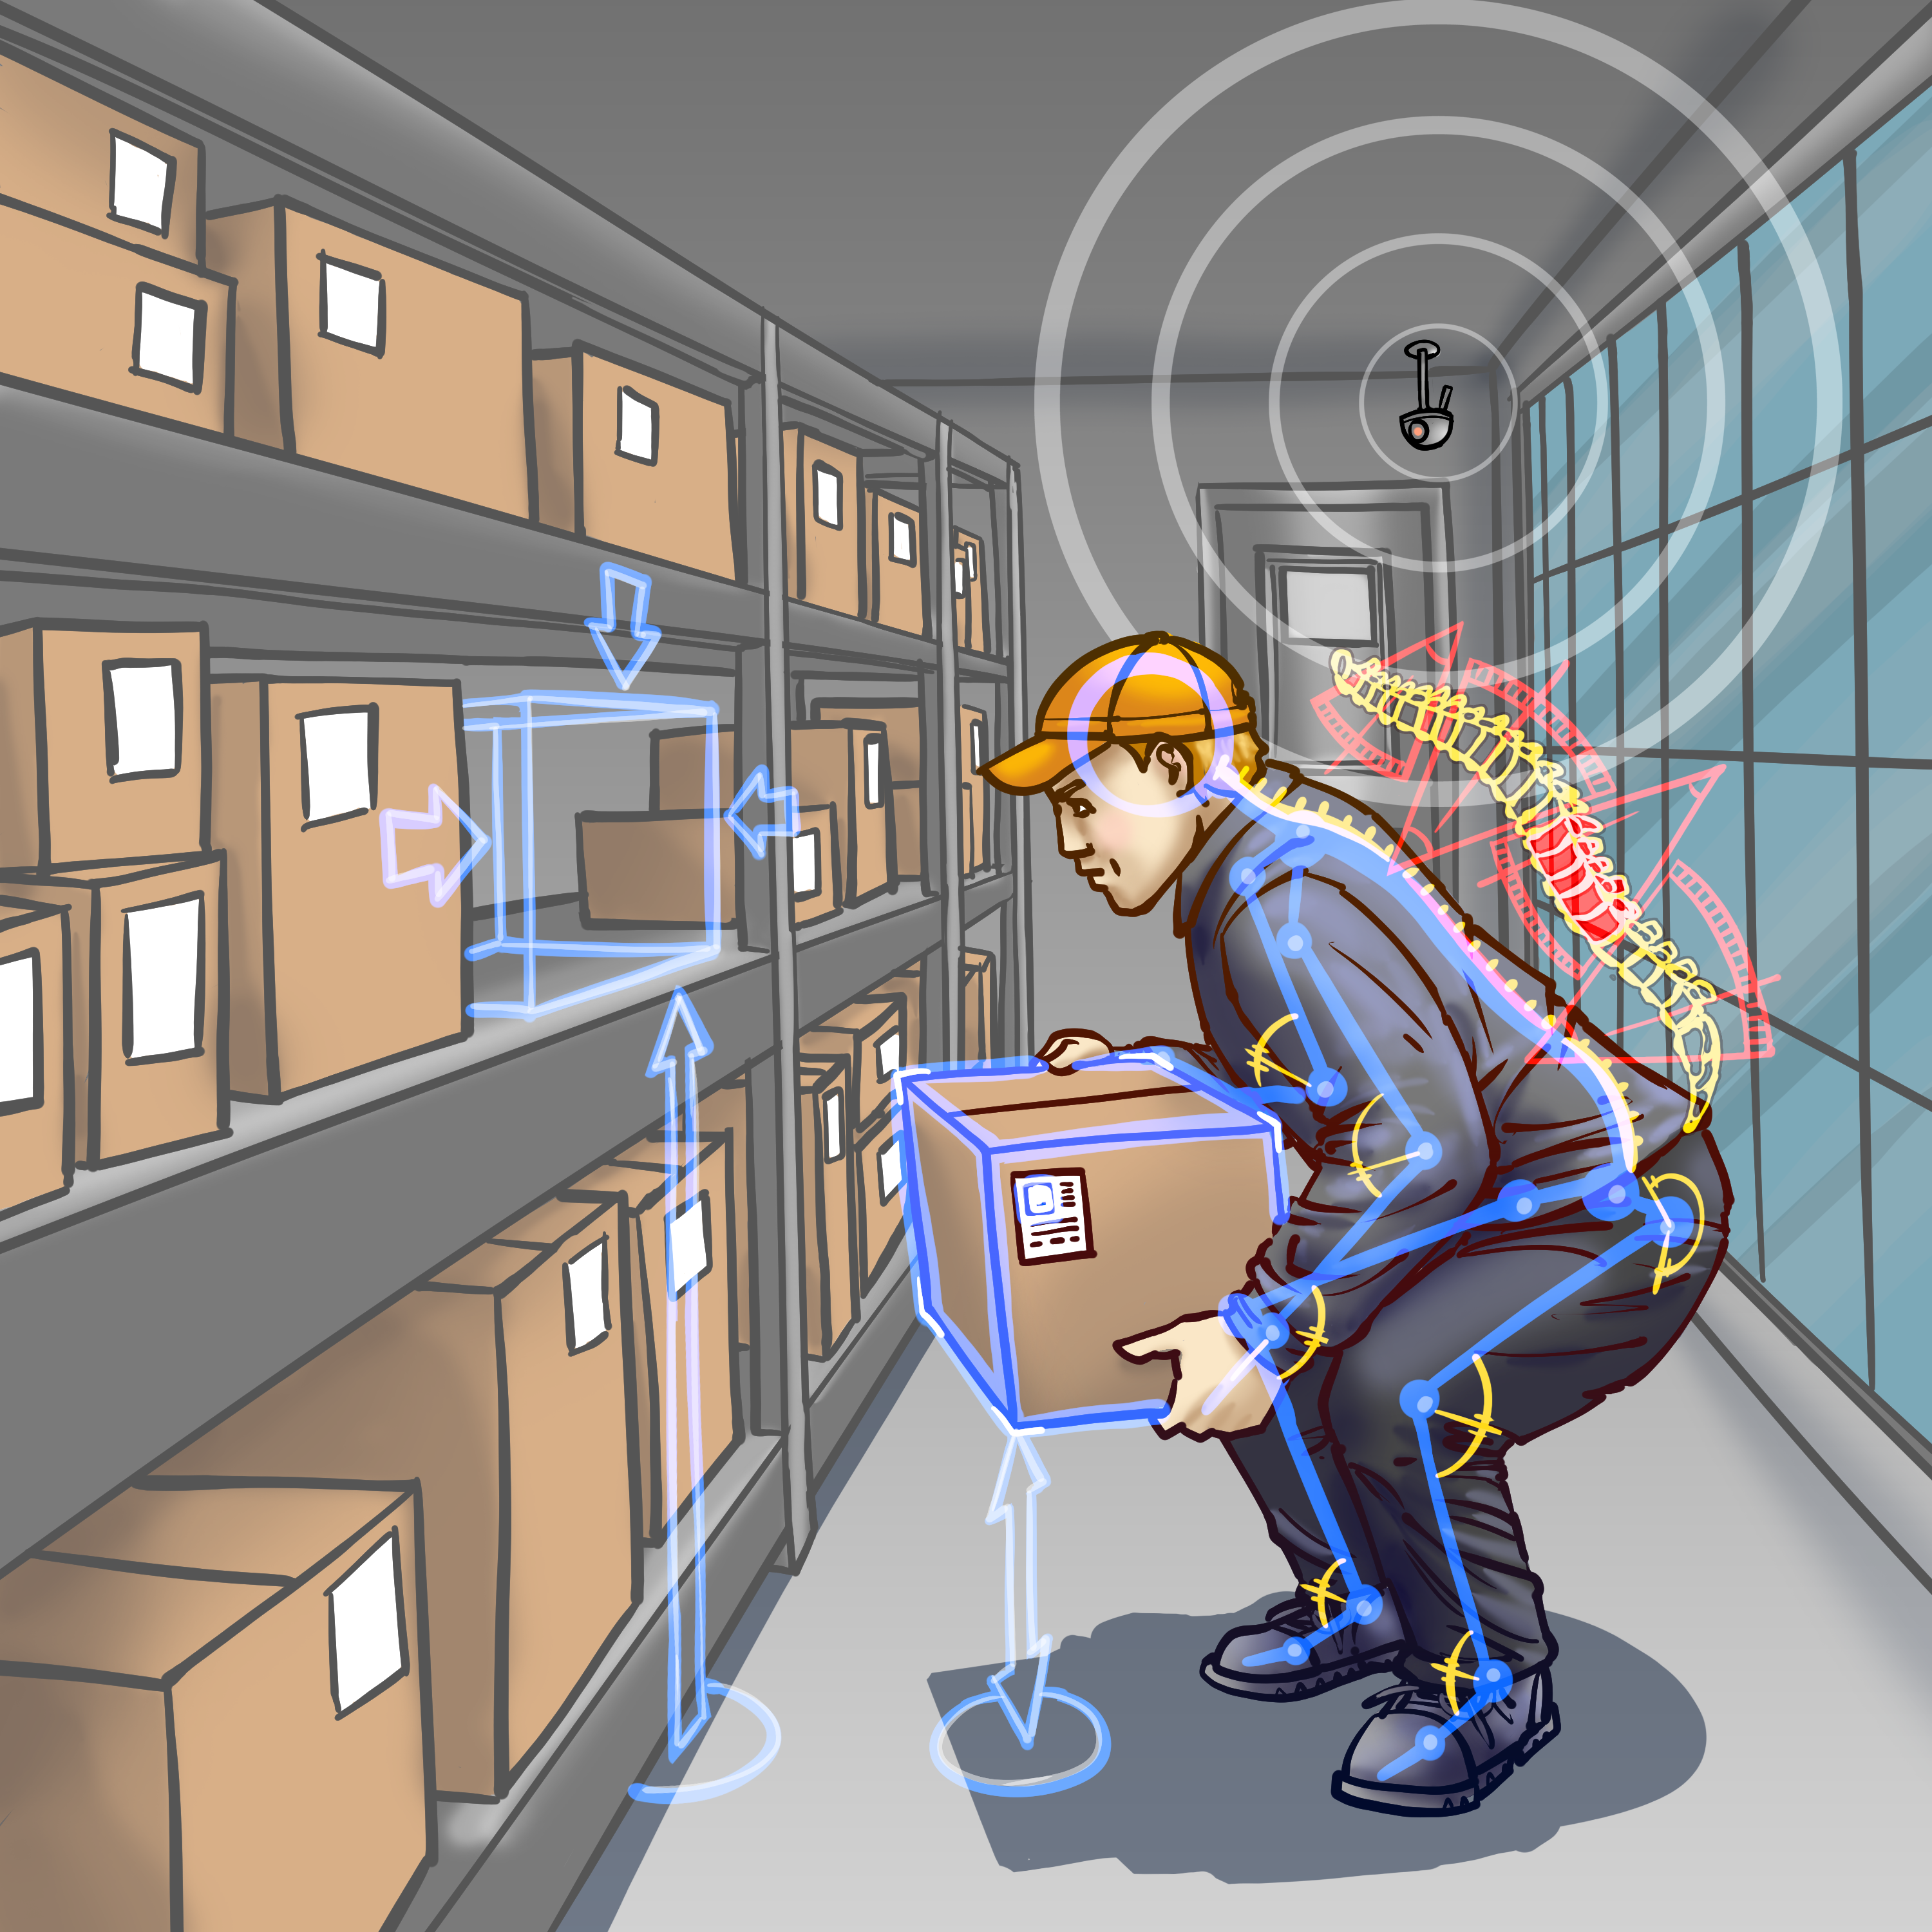
Markerless 3D motion capture from ordinary phone cameras for ergonomic safety analytics on the factory floor.

  • Built the MoCap product with a single colleague, winning a $150K/year contract with Siemens, and landed 3M as the company's first customer.
  • Experimented with monocular and multi-view approaches to extract 3D joint locations of workers; tackled monocular ambiguity with limb-length constraints and temporal smoothing.
  • Extended an open-source monocular synthetic 3D motion pipeline to multi-view in Blender (camera intrinsics, extrinsics, world and camera coordinates), and synthesized human motion in an anthropomorphic simulation for detailed ergonomics studies.
  • Built a mini MoCap system from two RGB-D cameras with confidence-based fusion.
Manual Assembly Copilot
Retrocausal

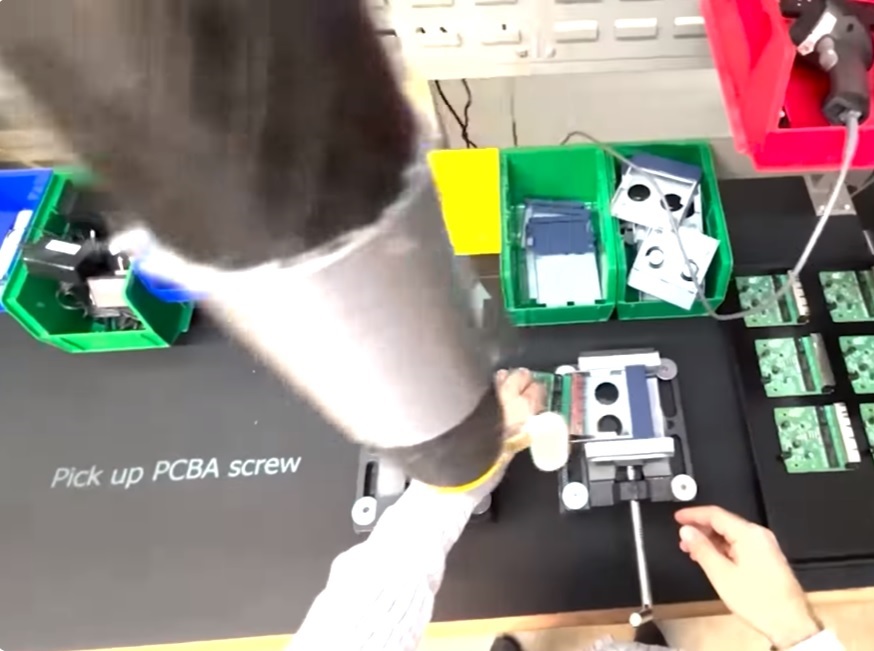
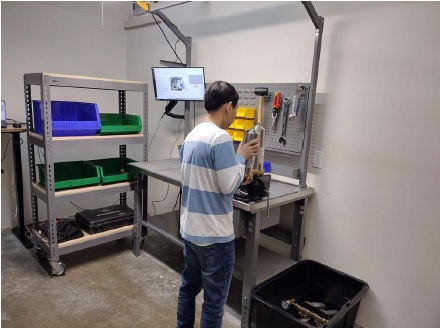
Mistake-proofing for manual assembly. It tracks each step of an assembly process and gives audible and visual alerts to help workers avoid mistakes.

  • Cut purchasing price by 150Γ— and deployment time by 180Γ— for a discrete manufacturing customer by replacing their sensor and visual inspection setup with a human action recognition model on Jetson Xavier / AGX.
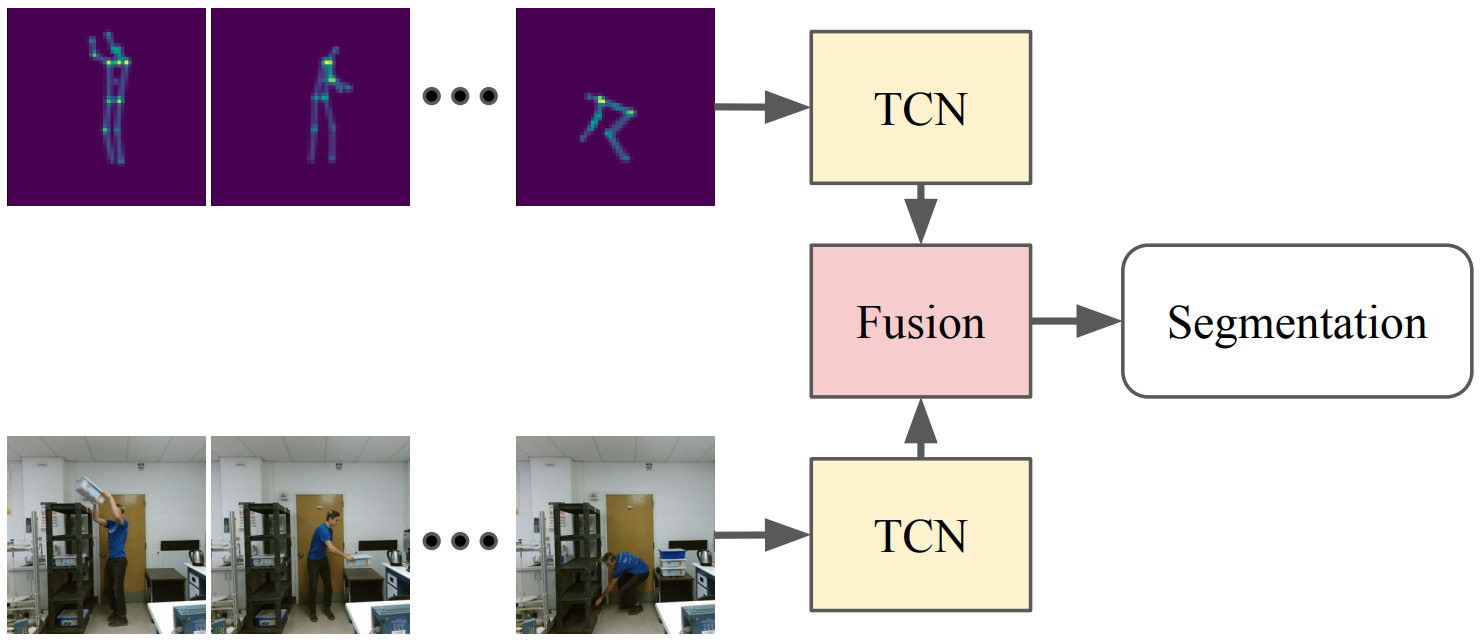
  • Built the human activity segmentation demo for the SBIR grant from NASA's Human Research Program.
  • Benchmarked video understanding models (3D CNN, I3D) against plain object detection (YOLO) and found that simple object detection works better for recognizing assembly steps on the factory floor.
Guidance Analytics and Trace
Retrocausal

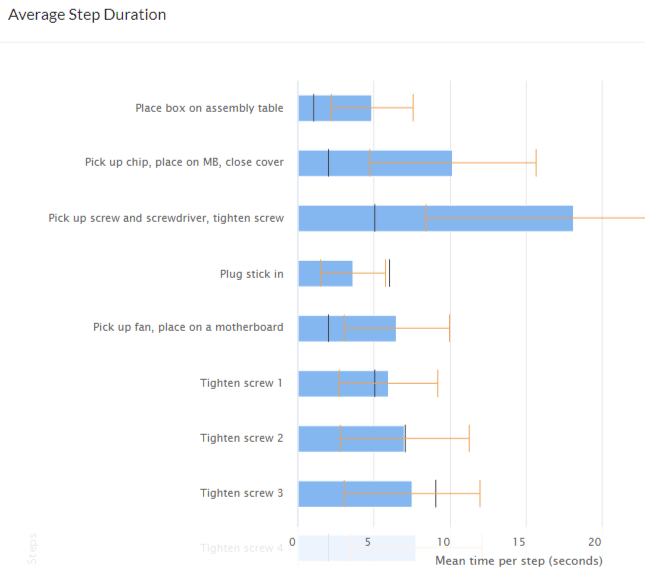
Collects timing data for every cycle on an assembly line, flags non-value-add work, finds the most efficient cycles and grades each session, so industrial engineers can improve their processes.

  • Wrote the algorithm for time and motion studies on discrete manufacturing assembly, giving step-level analytics.
  • Ran pilot projects with Honda, Suzuki and Nissan. Supervised the data collection and annotation team and kept improving the models to handle different factory floors.

Pet Projects I Vibecoded

Side projects I built and launched on my own. All four are live.

Google Maps for human introductions
30K+ nodes

What if everyone's phonebook were connected? Batcheet links contacts into one graph to test how well six degrees of separation holds in practice. It then finds the shortest chain of people between you and a hiring manager, so you can get a referral through people you know.

Graphs Next.js Referral Hiring
Time & weather database for remote teams
200 countries 7,000+ cities

Current time and weather for cities around the world, for remote workers whose teammates live in other timezones. Includes a world clock, meeting planner, timezone converter, city comparisons and public holiday calendars.

React Programmatic SEO Weather Data

ML experiments & earlier projects

Hindi/Urdu voice assistant that can see through your camera, built during Uplift AI's HackWeek. It uses function calling to understand what the camera sees and RAG (Pinecone) to remember past conversations. It only calls GPT-4 when a request involves visual input, and the base model handles everything else to keep token costs low.

RAG Function Calling Vision Hackathon

Predicts steering angle, detects objects, and classifies traffic lights at 4 FPS on a Jetson Nano. Bachelor thesis at NED University, 2020.

Computer Vision Edge AI
🚒

HuggingFace competition. Pushed mAP to 0.59 with YOLOv5/v7/v8. Key insight: training on evenly-tiled image crops enables zoomed-in detection.

Object Detection YOLO
🐝

Extracted bee centroids from heatmap images to synthesize YOLO-format bounding boxes, then trained YOLOv5 for detection.

Object Detection YOLO
πŸ€–

Built transformer decoder blocks one-by-one to deeply understand the architecture. Trained two models, one on Shakespeare and one on a subset of OpenWebText.

LLMs PyTorch
πŸ’¬

Fine-tuned GPT-2 on public Reddit conversations to capture sentiment on unfolding events in Pakistan. Hosted on HuggingFace Spaces.

NLP Fine-tuning

Publications

🧠
Muhammad Naufil
arXiv 2026 Multilingual LLMs Mechanistic Interpretability